Zipf's Law: Why a Few Words Rule Every Language
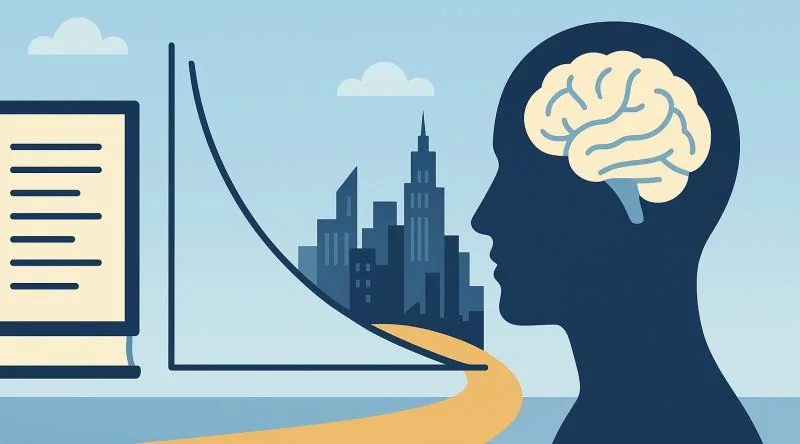
Zipf's Law is the observation, credited to Harvard linguist George Kingsley Zipf, that in any language the most common word appears roughly twice as often as the second most common, three times as often as the third, and so on down the list. It sounds like a curiosity about vocabulary. It turns out to describe something much bigger. The same steep curve shows up in city populations, company revenues, and the attention a handful of websites receive. Once you see the pattern, you start noticing it everywhere.
Zipf's Law says the most frequent item in a ranked list shows up about twice as often as the second, three times as often as the third, and so on. George Kingsley Zipf described it at Harvard in the 1930s. It applies to words, cities, firms, and web traffic. The pattern is regular, but it is a description, not a verdict on fairness.
- George Kingsley Zipf was a linguist at Harvard University who studied word frequencies in the 1930s.
- The law states that an item's frequency is roughly inversely proportional to its rank in a list.
- The pattern appears in language, city sizes, company revenues, and internet traffic.
- Zipf's work built on earlier observations by French engineer Jean-Baptiste Estoup.
- The law describes a distribution of outcomes; it does not claim those outcomes are just.
The Harvard Professor Who Found a Hidden Rule in Language
George Kingsley Zipf taught linguistics at Harvard University, and his name is attached to one of the strangest regularities in human behavior. The law credited to him is often dated to 1930, though that date is imprecise. The underlying principle predates him, and his two key books arrived in 1935 and 1949. So the man gets the label, but the idea was already floating in the air around him.
Here is what the law actually says, and it is beautifully simple. In any language, a word's frequency is inversely proportional to its rank in the frequency table. The most common word sits at the top. The second most common word shows up roughly half as often. The third appears about a third as often. The curve flows as 1 divided by rank, a clean slide from the giants at the top down to the stragglers at the bottom.
Think about what that means the next time you open your mouth. A handful of words do almost all the heavy lifting in every sentence you speak. The rest wait in the wings, called on rarely, if ever. Zipf's Law is the arithmetic behind that imbalance, and once you see it in language, you start noticing it everywhere else too.
Why the Brain Chooses Short Words
Think about the last sentence you spoke out loud. Odds are it leaned hard on a handful of tiny words: and, I, you, this. In Turkish, the same tiny pillars hold up everyday speech: ve, ben, sen, bu. There is a strong cross-linguistic tendency for the words we reach for most often to be the shortest ones, though the absolute version of that claim does not hold. Languages are full of exceptions, and frequency alone never guarantees brevity.
The reverse claim gets repeated a lot, and it is simply wrong as stated. The idea that rarely used words are long and complex falls apart the moment you look around. Yes, Turkish gives us monsters like epistemoloji, poststrüktürel and demokratikleştirilemeyen, and sure, those heavyweights tend to show up less in daily chatter. But plenty of rare words are short. Think of a technical term, a surname, a place name you have never said aloud. Brevity and rarity are not opposites. The pattern is a tendency, not a law carved into stone.
The Energy Argument Behind the Pattern
So why does the tendency exist at all? Here is where the original account gets interesting. Its argument runs like this: the brain is an organ with limited attention and limited memory. Survival demands speed. Speed demands brevity. Brevity demands simplicity. Under that reading, the short, frequent word is not a stylistic choice at all. It is a shortcut the mind takes so it does not exhaust itself.
Treat that as an interpretation, not a proven mechanism. It is a compelling story about energy efficiency, and it fits the data nicely, but nobody has put the brain on a scale and weighed the savings. What we can say with confidence is the shape of the distribution itself, and that shape is where Zipf's Law lives.
Picture the curve. Line up every word in a language by how often it appears. The top word sits alone at the peak. The second appears roughly half as often. The third, roughly a third as often. Frequency runs inversely proportional to rank, which is the standard formulation of Zipf's Law. The most common word is about twice as common as the second, three times as common as the third, and the pattern keeps sliding down the list.
The source frames the whole thing as a chain: survival equals speed, speed equals simplicity, simplicity equals frequency plus shortness. It is a tidy equation, and it is worth holding loosely. The tendency is real and it shows up across languages. The absolute version, the one that says frequent words are always short and rare words are always long, does not survive contact with actual vocabularies.
What does survive is the pull. Reach for a word a thousand times a day and your mouth, your memory and your listener all vote for the shortest option available. Reach for one twice in a lifetime and nothing pressures it to shrink. That asymmetry, gentle as it is, is enough to bend an entire lexicon into the curve.
Istanbul, Ankara, and the Shape of Cities
Zipf's Law shows up in maps just as clearly as it shows up in word lists. City populations follow what geographers call the rank-size rule: the largest city sits at the top, the second is smaller but grows in relation to the first, and the third is smaller still, with the curve bending the same way a word-frequency curve bends. Turkey fits this pattern almost too neatly. There are 81 provinces, yet roughly half the population crowds into a handful of centers, and Istanbul towers over all of them.
Now here is where the source gets bold. It calls Istanbul's size a "topological inevitability," a mathematical certainty produced by the Marmara Sea, the Black Sea, the Bosphorus, the Balkans-to-Middle East transition axis, trade routes, and its long run as an imperial administrative center. Geography and trade genuinely did most of the heavy lifting here, but the word "inevitability" is doing more work than the evidence supports. Empires chose their capitals. Trade routes shifted. The city we see today is the product of geography and a long chain of human decisions, not a single equation solving itself.
The source makes an even shakier claim about Ankara. It says Ankara's size is a mathematical result of its secondary-center function, a city that grew simply because it sits in Istanbul's shadow. That is wrong, or at least badly incomplete. Ankara's modern growth traces back to a deliberate political choice: its designation as the capital of the Republic of Turkey in 1923. A city does not swell to millions because a formula assigned it second place. It swells because someone decided to put the government there.
Then the source pushes further, into pure conjecture. If every city were the same size, it suggests, resources would scatter, the division of labor would collapse, information would slow to a crawl, and society would quietly consume itself. That is a striking image, and agglomeration economies are real, but the catastrophic ending is speculation, not a finding. Treat it as a thought experiment, not a law.
What holds up is the shape itself. Istanbul, Izmir, Bursa, Eskişehir, Gaziantep: the list keeps repeating the same fractal pattern, big node, smaller node, smaller node again. Whether you call that inequality or the price of efficiency depends on where you stand.
From Companies to the Internet: The Same Curve Everywhere
Follow the curve out of language and into money, and it barely changes shape. In market after market, a handful of companies controls the field while thousands of others claw for survival. That is not a moral failure of capitalism. It is the same 1/rank slope, just wearing a suit.
Here is the engine underneath it. A company grows, and trust grows with it. Trust makes investment easier, brand recognition cheaper, and scale economies kick in, so growth starts feeding itself. Dispersed power is waste. Concentrated power is efficiency. The system is not judging anyone; it is just flowing the way power always flows, along the path of least resistance.
The internet strips away the physical friction and shows the pattern in its rawest form. One video, one tweet, one photograph, one idea can reach millions while billions of other pieces of content vanish into a bottomless digital well. Online attention follows heavy-tailed distributions, and you can watch it happen in real time. A few viral names carry nearly everything; the rest thin out into silence.
Three pictures, one shape. In language, the story goes, a large share of everyday speech draws on just the first 50 most common words, though the exact share shifts with the corpus and the language. In Turkey, 81 provinces exist, yet about half the population crowds into a few centers. In economics, thousands of companies exist, yet power collects in a few hands. Same curve, three costumes.
And the algorithm? It gets blamed for everything, but it is not the villain here. It only optimizes human behavior. Whatever people share, click, and drift toward, the algorithm amplifies. The internet is a magnifying glass held over an instinct we already had.
Is Inequality a Moral Failure, or an Energy Law?
Here is where the argument lands its heaviest punch. The source behind this reading of Zipf's Law closes with a claim that is less linguistics than philosophy: equality is not always observed in nature, and nature picks efficiency over equality every time. Treat that as the essay's thesis, not as a settled fact. Nature has no agency and no preference. Still, the framing is the whole point of the piece, and it is worth following to the end.
The system, the source argues, is not moral. It runs on thermal, economic and cognitive optimization at once, and power simply flows along the path of least resistance. That is why the writer dismisses both camps at the same table. The person shouting that capitalism is evil and the person insisting the free market is sacred are, in this reading, making the same mistake: trying to understand a machine through a moral lens. A machine does not care whether you approve of it.
Then comes the quietest and most unsettling line in the whole piece. According to the source, what we call "choosing" is often just the mind's shortcut to avoid exhaustion. You think you picked the word, the city, the company, the video. The source says the order picked first, and you conformed to it. That is a philosophical conclusion, not a measurement, and it deserves to be read as one.
So where does that leave the moral question? The source never quite lets it go. If inequality is an optimization outcome, it is not automatically innocent. Calling something an energy law explains how a pattern forms. It does not tell you whether the pattern is just. That gap between description and judgment is the honest limit of this argument, and the source, for all its confidence, never closes it.
Frequently asked questions
What is Zipf's Law in simple terms?
Zipf's Law says a word's frequency is inversely proportional to its rank in the frequency table. The most common word appears roughly twice as often as the second, three times as often as the third, and the curve runs as 1 divided by rank. Real language corpora deviate somewhat from that clean pattern, but the 1/rank shape holds broadly.
Who was George Kingsley Zipf and what did he discover?
George Kingsley Zipf was a Harvard University professor whose name became attached to the law of word-frequency distribution. The principle predates him, and the often-cited 1930 date is imprecise; his key works appeared in 1935 and 1949, with Human Behavior and the Principle of Least Effort (1949) giving the standard formulation.
Why do the most common words in a language tend to be short?
There is a strong cross-linguistic tendency for frequent words to be short, and the brain's energy-efficiency argument explains why: a limited organ needs speed, speed needs brevity, and brevity needs simplicity. It is a tendency, not an absolute rule, so short rare words and long common words both exist.
How does Zipf's Law explain why a few cities like Istanbul grow so large?
City sizes follow a rank-size rule: the first city is largest, the second is smaller but grows in relation to it, and the third is smaller still. Istanbul's scale reflects its geographic and trade advantages, at the meeting of the Marmara Sea, the Black Sea, the Bosphorus and the Balkans-to-Middle East axis. The stronger claim that this was a "topological inevitability" is contested, since contingent historical and political choices also shaped the outcome.
Was Zipf's Law proven or is it just a pattern?
Zipf's Law is a standard formulation, not a theorem proved from first principles. Frequency proportional to 1/rank is the accepted description, and while real corpora deviate somewhat from the ideal curve, the inverse relationship between frequency and rank is consistently observed across languages and other ranked systems.
Did Zipf's Law predict how internet attention would concentrate?
Yes. Online content popularity follows heavy-tailed power-law distributions: a few videos, tweets or ideas reach millions while billions of other pieces of content are lost. This is well documented and matches the same 1/rank pattern seen in language and city sizes, so the internet makes the concentration visible rather than creating it.
Why does Zipf's Law suggest inequality is not a moral failure?
This is the source's philosophical argument, not a verified fact. It holds that concentration reflects energy efficiency rather than injustice, and that scattered power wastes resources. Treat it as an assertion: nature has no agency, and both equality and inequality appear in natural systems, so the moral reading remains open to dispute. Editorial note: Details that remain unconfirmed, including specific numerical values and historical attributions, are presented here as approximations rather than settled facts.
Got a take on this? Add your voice to the conversation below →
No comments yet. Be the first.